Research
Forgetting, derived from first principles.
Cognition is not a wrapper with a memory bolt-on. It is built on a line of work that treats learning as controlled diffusion on a multilayer cognitive manifold, where the forgetting curve, the detail-before-schema ordering, and the limit on how hard you can intervene all fall out of one operator and its spectrum. This page is the research, the figures, and the honest line between what is proven and what is shipped.
Mode-Selective Memory Decay from Multilayer Neural Architecture: A Spectral Theory
Detailed episodic memories decay faster than schematic ones across behavioral, neuroimaging, and lesion paradigms, yet no formal model has derived that rate separation from neural architecture. This paper does. Memory is modeled as controlled state evolution on a product cognitive manifold with a multilayer graph Laplacian. The Kronecker-sum structure yields an additive eigenvalue decomposition in which high-frequency detail modes decay exponentially faster than low-frequency schema modes, the spectral gap of the weakest layer sets the global forgetting rate, and a stability bound constrains intervention before reconsolidation-like overwrite. The Weibull curve emerges naturally, rather than being fitted.
Deployed platform data (1,500+ users, 4,200 learning events) supports the derived relationship between knowledge-graph spectral gap and observed retention: r = 0.71, p < 0.001. The detail-before-schema ordering is a consequence of multilayer architecture, not an empirical regularity that needed fitting.
1# mode_selective_decay.py2# The model, in code. Each law (see the math tab) maps to a few lines here.34import numpy as np56# 1 Cognition operator: dPhi/dt = (-L + U) @ Phi7def step(phi, L, U, dt):8 # L is passive forgetting; U is bounded intervention.9 return phi + dt * (-L + U) @ phi1011# 2 Multilayer Laplacian: L = Lb (x) Ic (x) Is + ... (Kronecker sum)12def multilayer_laplacian(Lb, Lc, Ls):13 Ib, Ic, Is = [np.eye(len(M)) for M in (Lb, Lc, Ls)]14 return (np.kron(np.kron(Lb, Ic), Is)15 + np.kron(np.kron(Ib, Lc), Is)16 + np.kron(np.kron(Ib, Ic), Ls))1718# 3 Spectral gap: lambda1(L) = min(lambda1_b, lambda1_c, lambda1_s)19def spectral_gap(Lb, Lc, Ls):20 gap = lambda M: np.sort(np.linalg.eigvalsh(M))[1]21 return min(gap(Lb), gap(Lc), gap(Ls)) # the weakest layer wins2223# 4 Forgetting curve: R(t) = exp(-(t / S) ** beta), S = 1 / lambda124def retention(t, lam1, beta=1.0):25 S = 1.0 / lam126 return np.exp(-(t / S) ** beta) # Weibull, not fitted2728# 5 Stability bound: ||U|| < lambda1 => the state contracts29def is_stable(U, lam1):30 return np.linalg.norm(U, 2) < lam1 # omega = lambda1 - ||U|| > 0
Same five laws, two views. Toggle decay.py and math: every equation is a few lines of code.
Deep dive, theory spine
The Cognitive Operator
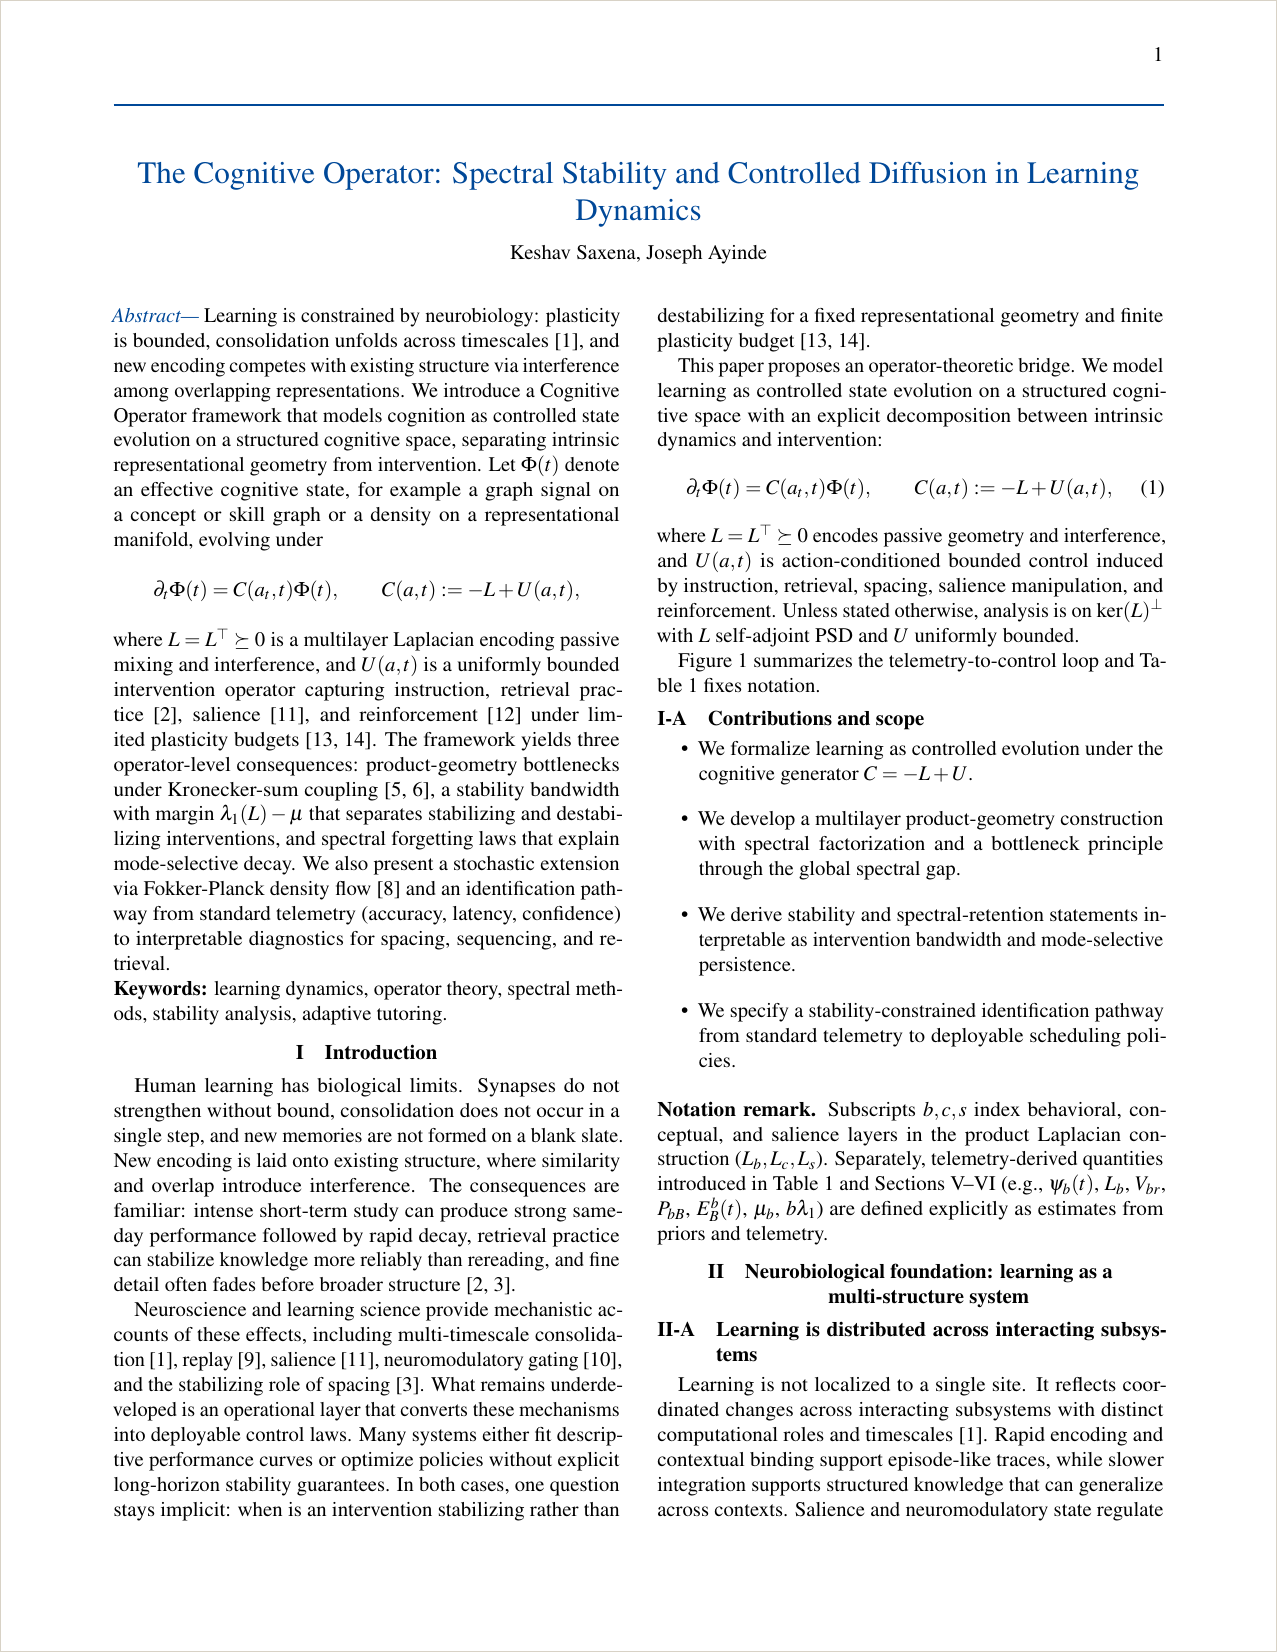
This is the theoretical spine of the product. It proposes an operator-theoretic bridge between neurobiology and deployable scheduling: learning is modeled as controlled state evolution on a structured cognitive space, with an explicit split between intrinsic geometry (the Laplacian L, encoding passive mixing and interference) and intervention (U, the action-conditioned, bounded control induced by instruction, retrieval, spacing, salience, and reinforcement under limited plasticity budgets).
The payoff is a single object, the cognitive generator C = -L + U, that turns familiar but informal effects (intense short-term study followed by rapid decay, retrieval practice stabilizing better than rereading, fine detail fading before broad structure) into operator-level statements you can compute with and act on.
What it establishes
- Formalizes learning as controlled evolution under the cognitive generator C = -L + U, separating intrinsic representational geometry from intervention.
- Builds a multilayer product-geometry construction with spectral factorization and a bottleneck principle through the global spectral gap.
- Derives stability and spectral-retention statements interpretable as intervention bandwidth and mode-selective persistence.
- Specifies a stability-constrained identification pathway from standard telemetry (accuracy, latency, confidence) to deployable scheduling policies, with a Fokker-Planck stochastic extension.
Deep dive, the full treatise
The spectral physics of intelligence
The 71-page treatise that situates the operator inside a single discipline the authors name the spectral physics of intelligence. Cognition spans neural, conceptual, and social layers, but existing models isolate them, and machine learning fragments learning the same way: contextual bandits treat tasks as isolated actions, spaced-repetition systems treat memory as exogenous decay, and transformers treat tokens as static sequences rather than evolving cognitive states.
This paper unifies all three, twin-embedded contextual bandits (decision-making), multilayer graph-operator dynamics (memory and forgetting), and Bayesian memory control (inference), as facets of controlled diffusion on structured Riemannian manifolds, bridging functional analysis, stochastic PDEs, optimal transport, spectral geometry, information theory, and computational neuroscience.
Proven results
- Proves exponential stability of the cognitive semigroup via hypocoercivity.
- Establishes minimax-optimal Bayesian inference of the spectral parameters that set retention (the DFCP filter).
- Derives regret bounds coupling exploration-exploitation to the curvature of the conceptual manifold (the Cipher twin-embedded bandit), with sublinear growth O(sqrt(T log T)).
- Proves convergence of the coupled operator-bandit-memory system, and draws explicit links to deep generative models, reinforcement-learning world models, and geometric deep learning.
Why it matters
The forgetting curve is not academic. It is a multi-billion-dollar leak.
The same decay our model derives is what quietly drains teams: knowledge evaporates faster than people can recapture it, and the spend meant to fix it mostly does not stick. Measured findings, not projections, collected in our white paper, The Invisible Data Layer.
90%
of new training is forgotten within a single week.
Ebbinghaus, replicated 2025
84-90%
of sales training knowledge is lost within 90 days, after the budget is already spent.
Josh Bersin Company
<40%
of acquired learning is still in use even 12 months later.
Saks & Belcourt
~20%
of learning ever transfers back into actual day-to-day work.
Detterman & Sternberg
$1,400+
spent per employee per year on training, yet only 27% of companies say they build the skills they need.
Josh Bersin
59 / 100
workers will need reskilling by 2030; 11 of them are unlikely to ever receive it.
WEF Future of Jobs 2025
Status
We separate what is shipped from what is still research.
A science page earns trust by being explicit about what is live, what is measured, and what is still being hardened. Here is the honest line.
Implemented
in production
MCP install, hosted agent instructions, human-approved SKILL.md, author attribution, cross-agent reuse, and outcome reporting.
Measured
receipt-gated
Token and time savings are claimed only when receipts tie a reused skill to a real outcome. The call ledger shows the basis.
Experimental
active research
Decay and freshness weights are an active research surface. They surface as confidence and a refresh prompt, not hidden certainty.
Validated
r = 0.71, p < 0.001
Deployed platform data supports the derived spectral-gap-to-retention relationship across 4,200 learning events.